

Applied AI engineering
Practical AI that ships, and keeps running.
Custom LLMs, retrieval, and agents that do real work inside your systems. Built by senior engineers who run self-hosted LLM inference in production today, and deployed where you choose: AWS, Google Cloud, or your own hardware.
 Google
 EA
 Twitch
What we build
Agents that do the work. Not chatbots.
Every system we build has a job, a measure of success, and a cost you can plan for.
Custom LLMs
Models shaped to your domain, your data, and your budget.
- Model selection and fine-tuning
- Training data preparation
- Structured output for real systems
Retrieval and RAG
Answers grounded in your documents and records, not the open internet.
- Embeddings and vector search
- Ingestion pipelines for your sources
- Citations and access control
Agents and workflow automation
Systems that do the work inside the tools your team already uses.
- Tool-using agents with clear limits
- Integration with your APIs and data
- Human review where it matters
Evals, safety, and cost control
The work that keeps AI in production after the demo.
- Evaluation suites and regression tests
- Guardrails, moderation, and fallbacks
- Usage tracking and cost per request
Where it runs
Your cloud, or your own hardware.
We pick the deployment that fits your data, your compliance needs, and your budget, and we can move between them as you grow.
- AWS
Amazon Bedrock
Managed foundation models inside your AWS account, wired to your data and your IAM. The fastest path if you already run on AWS.
- Google Cloud
Vertex AI
Gemini and open models on Google Cloud, next to the data you already keep there.
- Your hardware · Our specialty
Self-hosted open-weight models
Open-weight LLMs served on your own GPUs with vLLM-class inference. Predictable cost, no per-token bill, and your data never leaves the building. We run this in production today.
Proof
We run production AI for a global audience.
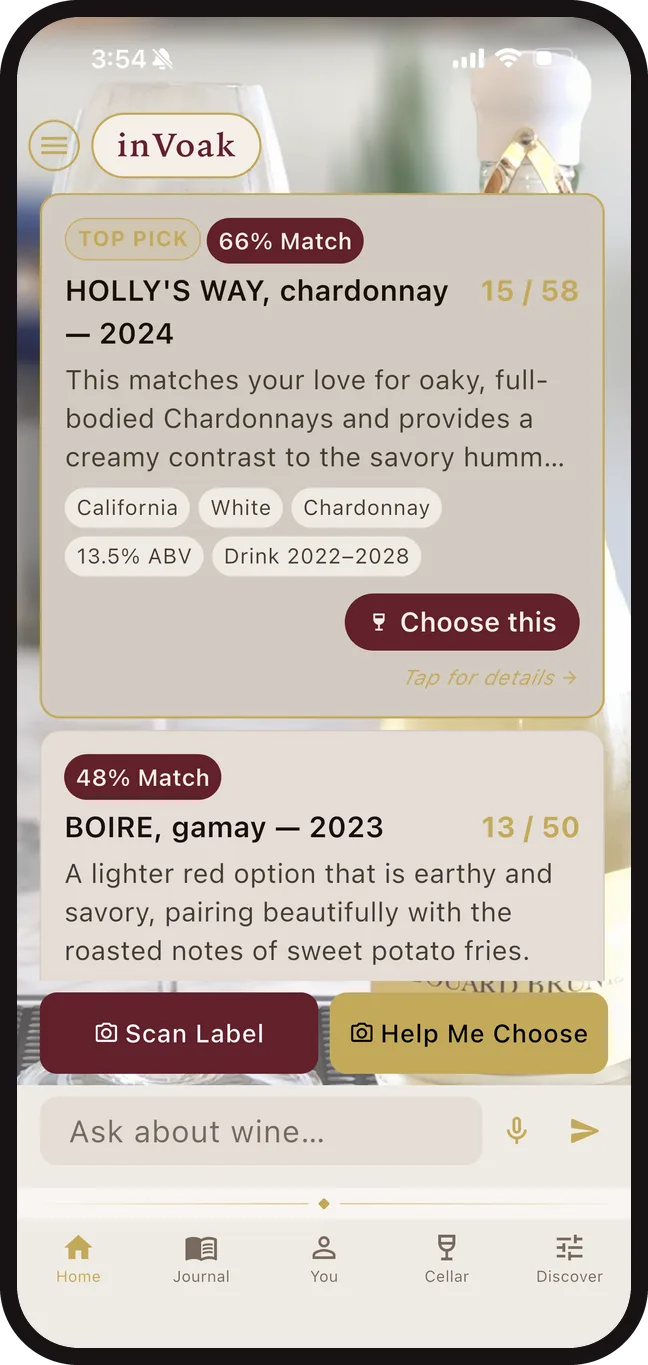
inVoak, our own product, puts LLMs to work for real users every day: reading wine labels and menus, answering questions in a conversational sommelier, and ranking recommendations against each user’s palate. It runs self-hosted LLM inference in production, in 20 languages across 170+ countries, with GDPR, CCPA, and DSA coverage.
Flagship product
 inVoak
Your personal AI wine sommelier.
Designed, built, and operated entirely in house. Live on iOS, Android, and the web in 170+ countries and 20 languages, with production AI at its core.
How we work
Start small. Scale what works.
Fixed-scope pilot
One use case, real data, and a working system in weeks. A clear deliverable, a clear price, and an honest read on whether it is worth scaling.
Embedded AI engineer
A senior engineer joins your team for weeks or months, working in your repos and your rituals, to take AI features from prototype to production.
- 01
Scope
A short call, then a written plan with milestones, risks, and a price.
- 02
Prove
An evaluation set built from your data, so progress is measured, not guessed.
- 03
Ship and run
Production deployment, monitoring, and cost tracking. We stay through launch.
Let’s build
Have an AI idea that needs to ship?
Tell us the problem, the data you have, and where it needs to run. A founder will reply personally.